Databricks
Databricks data-engineer-professional
Databricks Certified Data Engineer Professional
Practice questions with verified answers, detailed explanations, and community discussions.
- 257
- Questions
- today
- Last updated
- Guest
- Your plan
25 free questions
Question 11 of 257
Topic 1: Databricks Certified Data Engineer ProfessionalTopic 1: Databricks Certified Data Engineer Professional
The data engineering team has configured a job to process customer requests to be forgotten (have their data deleted). All user data that needs to be deleted is stored in Delta Lake tables using default table settings.
The team has decided to process all deletions from the previous week as a batch job at 1am each Sunday. The total duration of this job is less than one hour. Every Monday at 3am, a batch job executes a series of VACUUM commands on all Delta Lake tables throughout the organization.
The compliance officer has recently learned about Delta Lake's time travel functionality. They are concerned that this might allow continued access to deleted data.
Assuming all delete logic is correctly implemented, which statement correctly addresses this concern?
Choose your answer
Pick an answer to check it, or press Show answer to see the correct one.
Question 12 of 257
Topic 1: Databricks Certified Data Engineer ProfessionalTopic 1: Databricks Certified Data Engineer Professional
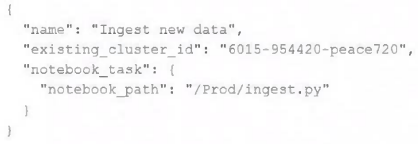
A junior data engineer has configured a workload that posts the following JSON to the Databricks REST API endpoint 2.0/jobs/create.
Assuming that all configurations and referenced resources are available, which statement describes the result of executing this workload three times?
Choose your answer
Pick an answer to check it, or press Show answer to see the correct one.
Question 13 of 257
Topic 1: Databricks Certified Data Engineer ProfessionalTopic 1: Databricks Certified Data Engineer Professional
An upstream system is emitting change data capture (CDC) logs that are being written to a cloud object storage directory. Each record in the log indicates the change type (insert, update, or delete) and the values for each field after the change. The source table has a primary key identified by the field pk_id.
For auditing purposes, the data governance team wishes to maintain a full record of all values that have ever been valid in the source system. For analytical purposes, only the most recent value for each record needs to be recorded. The Databricks job to ingest these records occurs once per hour, but each individual record may have changed multiple times over the course of an hour.
Which solution meets these requirements?
Choose your answer
Pick an answer to check it, or press Show answer to see the correct one.
Question 14 of 257
Topic 1: Databricks Certified Data Engineer ProfessionalTopic 1: Databricks Certified Data Engineer Professional
An hourly batch job is configured to ingest data files from a cloud object storage container where each batch represent all records produced by the source system in a given hour. The batch job to process these records into the Lakehouse is sufficiently delayed to ensure no late-arriving data is missed. The user_id field represents a unique key for the data, which has the following schema:
user_id BIGINT, username STRING, user_utc STRING, user_region STRING, last_login BIGINT, auto_pay BOOLEAN, last_updated BIGINT
New records are all ingested into a table named account_history which maintains a full record of all data in the same schema as the source. The next table in the system is named account_current and is implemented as a Type 1 table representing the most recent value for each unique user_id.
Assuming there are millions of user accounts and tens of thousands of records processed hourly, which implementation can be used to efficiently update the described account_current table as part of each hourly batch job?
Choose your answer
Pick an answer to check it, or press Show answer to see the correct one.
Question 15 of 257
Topic 1: Databricks Certified Data Engineer ProfessionalTopic 1: Databricks Certified Data Engineer Professional
A table in the Lakehouse named customer_churn_params is used in churn prediction by the machine learning team. The table contains information about customers derived from a number of upstream sources. Currently, the data engineering team populates this table nightly by overwriting the table with the current valid values derived from upstream data sources.
The churn prediction model used by the ML team is fairly stable in production. The team is only interested in making predictions on records that have changed in the past 24 hours.
Which approach would simplify the identification of these changed records?
Choose your answer
Pick an answer to check it, or press Show answer to see the correct one.